Machine Learning Primer
From the fundamentals of neural networks through reinforcement learning, object detection and recognition, and generative models, explained through both implementation and math.
Find a reading order in the learning guides → Search this field →
Specialized topics in this field
 Machine Learning Primer
September 8, 2026
Lab
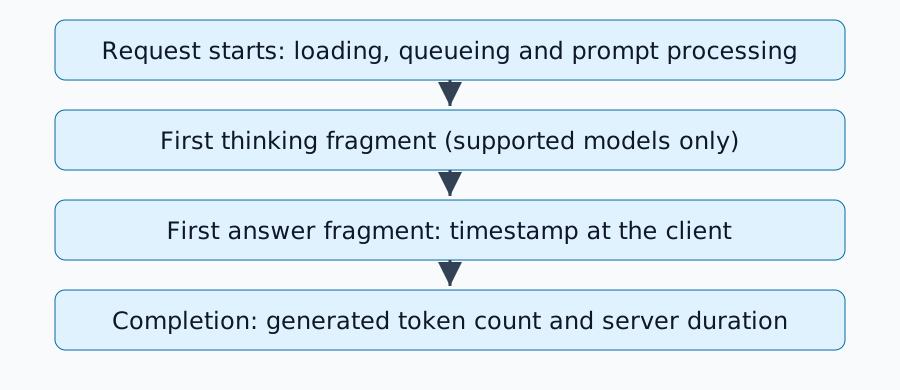
Benchmark local LLMs: first response, generation rate and memory
Measure first answer content separately from generation rate and control residency, caching and memory conditions.
Hands-on · 3 min Machine Learning Primer
September 5, 2026
Object Detection & Semantic Segmentation Primer — Reading "What Is Where" From an Image
Object Detection draws boxes around things; Semantic Segmentation colors in every pixel by meaning. From the difference between the two, through Instance and Panoptic Segmentation, the lineage from R-CNN to YOLO, DETR and DINO, all the way to their 3D point-cloud counterparts — a systematic tour of the fundamentals of scene understanding.
Fundamentals · 14 min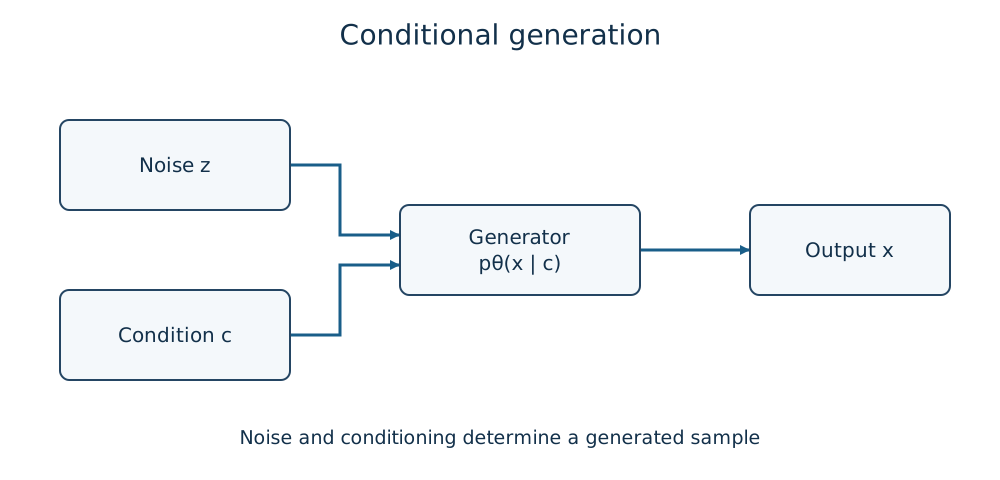 Machine Learning Primer
September 4, 2026
Machine Learning Primer: Generative Models
Generative models represent data distributions and create conditional outputs. Learn likelihood, VAE, GAN, diffusion, evaluation, provenance, and safety.
Fundamentals · 4 min Machine Learning Primer September 4, 2026Machine Learning Primer: Foundations — Designing Data, Loss, and Generalization
Machine learning is not just model selection: define the task, data split, loss, evaluation, and deployment change.
Fundamentals · 5 min Machine Learning Primer September 4, 2026A Thorough Guide to SegFormer — Why a Transformer Without Positional Encoding Works for Segmentation
This article breaks down SegFormer, introduced by NVIDIA, The University of Hong Kong, and collaborators at NeurIPS 2021, based on the original paper. We examine the hierarchical MiT encoder without positional encoding, the parameter-efficient All-MLP decoder, the effective receptive field, and the measured mIoU, parameter counts, and compute from B0 to B5 with equations.
Fundamentals · 9 min Machine Learning Primer September 4, 2026YOLO11 Explained in Depth — What Did C3k2 and C2PSA Change from YOLOv8?
Break down Ultralytics YOLO11 using official documentation and primary sources: C3k2, C2PSA, anchor-free detection, DFL/CIoU losses, and measured benchmarks for n/s/m/l/x.
Fundamentals · 11 min Machine Learning Primer September 4, 2026Machine Learning Primer: Neural Network Basics
Neural networks stack affine transforms and nonlinear activations, then reduce loss by backpropagation and gradient-based optimization.
Fundamentals · 5 min Machine Learning Primer September 4, 2026Machine Learning Primer: Pose Estimation
Pose estimation infers human or object keypoints and 6D pose from images. This primer covers coordinates, losses, occlusion, evaluation, and safety.
Fundamentals · 4 min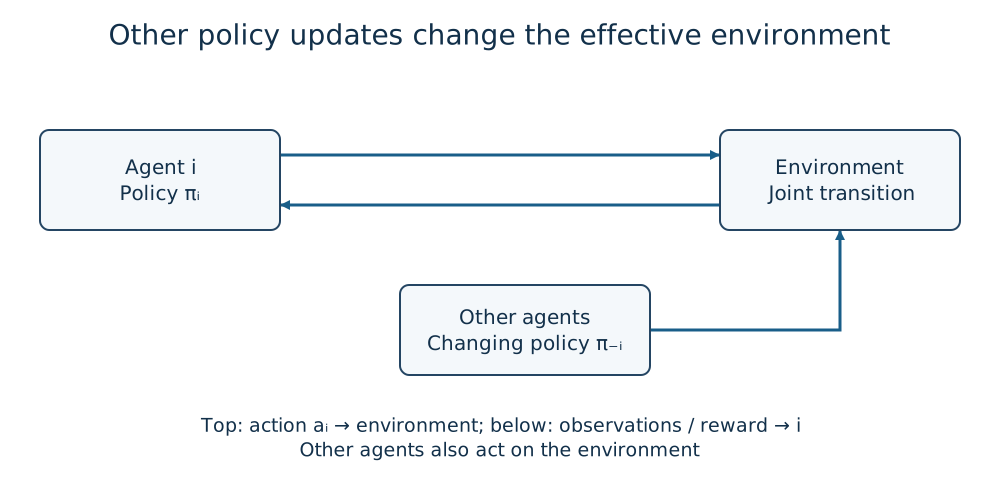 Reinforcement Learning Primer
September 4, 2026
Multi-Agent Reinforcement Learning Primer — Optimizing in a World Where the Other Side Is Learning Too
When multiple agents learn at the same time, a single-agent MDP no longer holds. This article organizes non-stationarity, cooperative/competitive/mixed settings, CTDE, the credit-assignment problem, and MADDPG and QMIX, with equations and diagrams.
Fundamentals · 8 min Reinforcement Learning Primer September 4, 2026π0 Explained — How Flow Matching Changed VLA Action Generation
A source-based technical guide to Physical Intelligence's π0: the PaliGemma VLM and dedicated Action Expert, continuous action generation with conditional flow matching, cross-embodiment training across seven robot types, and the difference from autoregressive VLA models such as RT-2 and OpenVLA.
Fundamentals · 11 min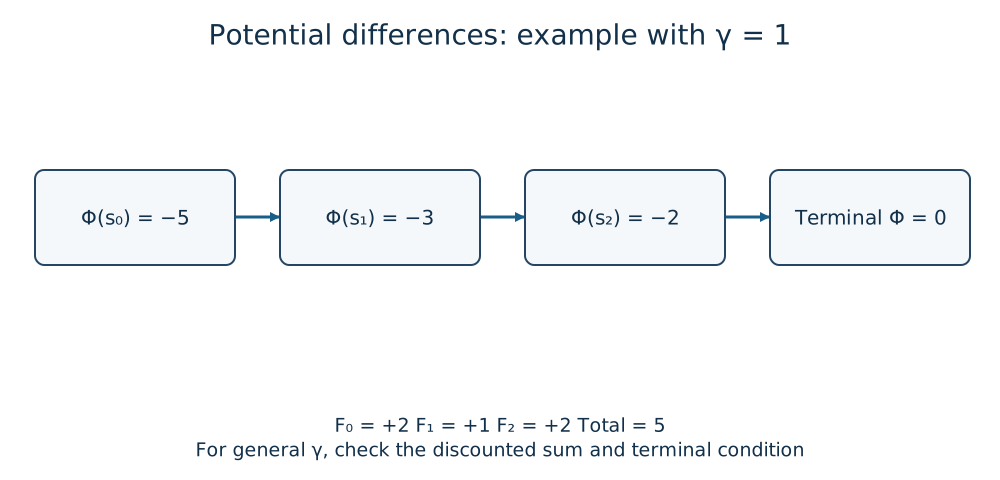 Reinforcement Learning Primer
September 4, 2026
Reward Design Primer — Why "What to Maximize" Is the Hardest Part of RL
In reinforcement learning implementations, reward-function design more often determines the outcome than the algorithm does. This article organizes sparse vs. dense reward, the policy invariance of potential-based reward shaping, real cases of reward hacking, inverse reinforcement learning, and constrained RL.
Fundamentals · 8 min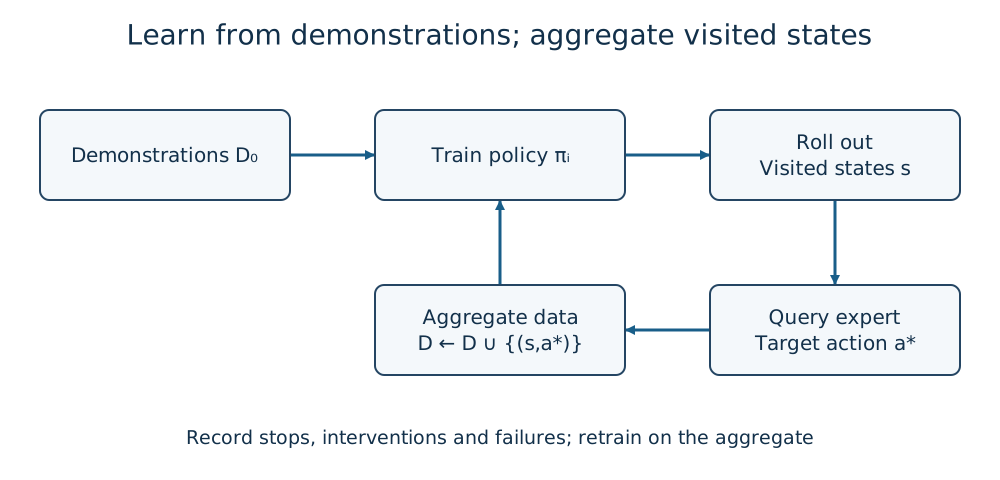 Reinforcement Learning Primer
September 3, 2026
Reinforcement Learning Primer: Imitation Learning and Inverse Reinforcement Learning
Behavior Cloning, DAgger, and inverse reinforcement learning use demonstrations when rewards are hard to write. This primer covers covariate shift, reward inference, VLA connections, evaluation, safety, and data provenance.
Fundamentals · 5 min Reinforcement Learning Primer September 3, 2026Reinforcement Learning Basics — MDPs, Bellman Equations, and Exploration for Robots
Reinforcement learning is a closed loop in which an agent chooses actions from observations and maximizes delayed rewards. This primer explains MDPs, value functions, policies, Bellman equations, exploration versus exploitation, reward design, and the path from simulation to a real robot.
Fundamentals · 6 min Reinforcement Learning Primer September 3, 2026Model-Based Reinforcement Learning and Sim-to-Real
World models, prediction error, MPC, domain randomization, system identification, and safety monitoring for real machines.
Fundamentals · 4 min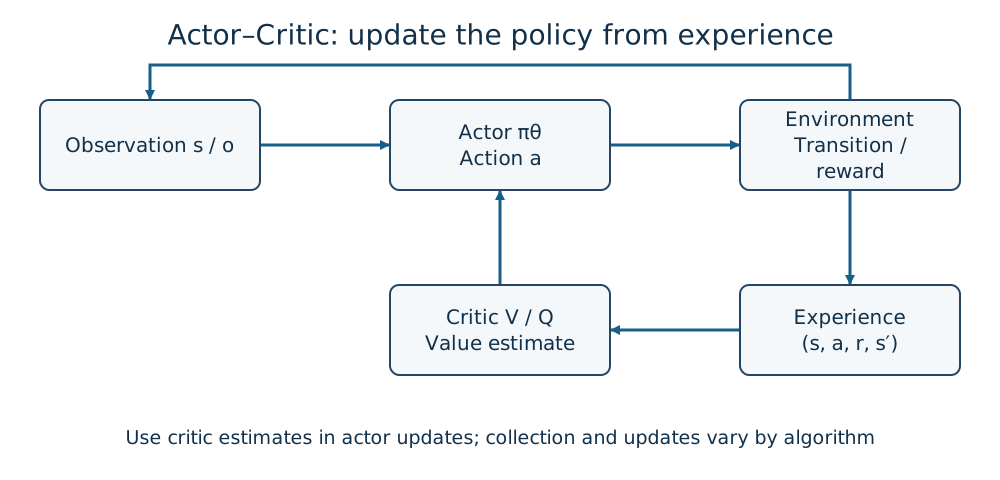 Reinforcement Learning Primer
September 3, 2026
Policy Gradients, PPO, and SAC — Stable Continuous Control for Robots
Policy gradients update a policy directly so that steering, thrust, and joint torque can remain continuous. This article connects Actor-Critic, PPO, and SAC, then covers clipping, entropy regularization, evaluation, and the safety boundary for Sim-to-Real transfer.
Fundamentals · 5 min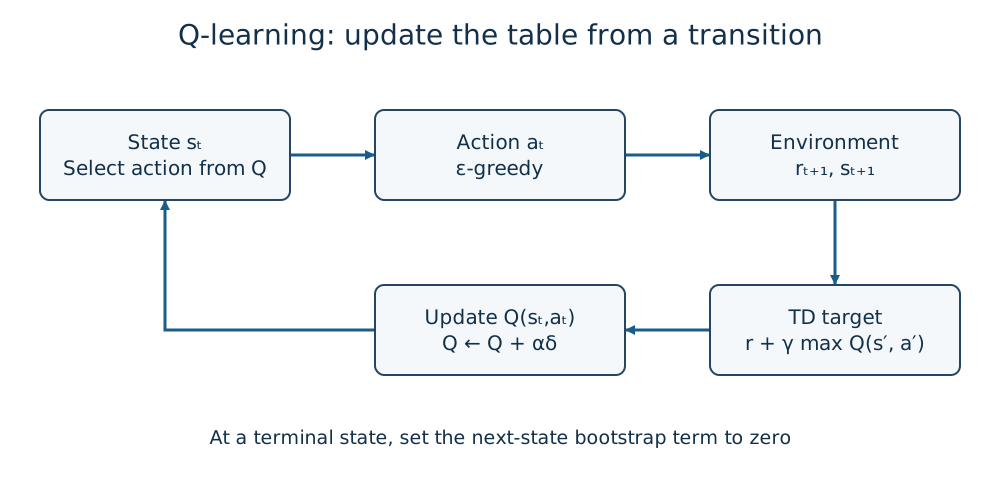 Reinforcement Learning Primer
September 3, 2026
Q-Learning and DQN — From a Q-Table to Deep Reinforcement Learning
Q-learning updates action values with the Bellman optimality target. This primer follows the path from a tabular Q-table to a Deep Q-Network, explaining experience replay, target networks, overestimation, and safe placement in a robot stack.
Fundamentals · 5 min