Reinforcement Learning Primer
MDPs and Bellman equations through deep RL, imitation learning, and Sim-to-Real, always tied to robot applications.
Find a reading order in the learning guides → Search this field →
 Reinforcement Learning Primer
September 4, 2026
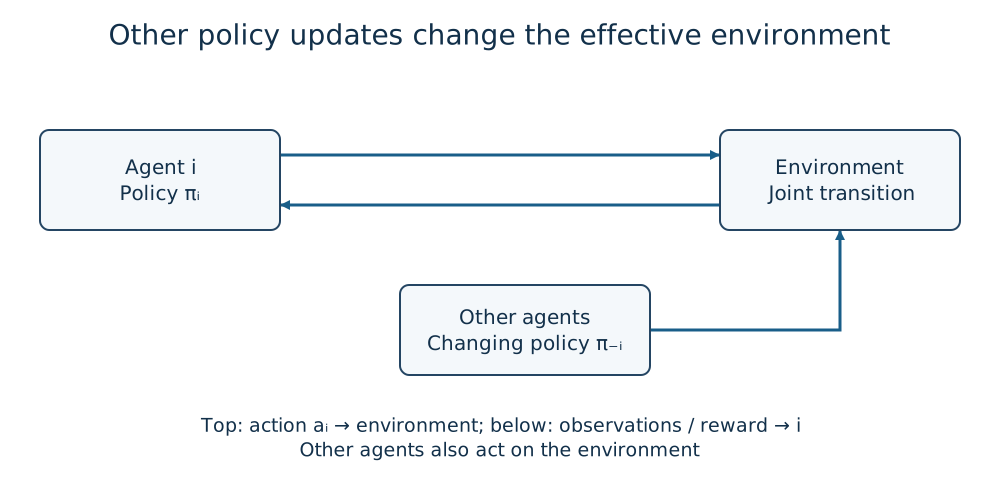
Multi-Agent Reinforcement Learning Primer — Optimizing in a World Where the Other Side Is Learning Too
When multiple agents learn at the same time, a single-agent MDP no longer holds. This article organizes non-stationarity, cooperative/competitive/mixed settings, CTDE, the credit-assignment problem, and MADDPG and QMIX, with equations and diagrams.
Fundamentals · 8 min Reinforcement Learning Primer September 4, 2026π0 Explained — How Flow Matching Changed VLA Action Generation
A source-based technical guide to Physical Intelligence's π0: the PaliGemma VLM and dedicated Action Expert, continuous action generation with conditional flow matching, cross-embodiment training across seven robot types, and the difference from autoregressive VLA models such as RT-2 and OpenVLA.
Fundamentals · 11 min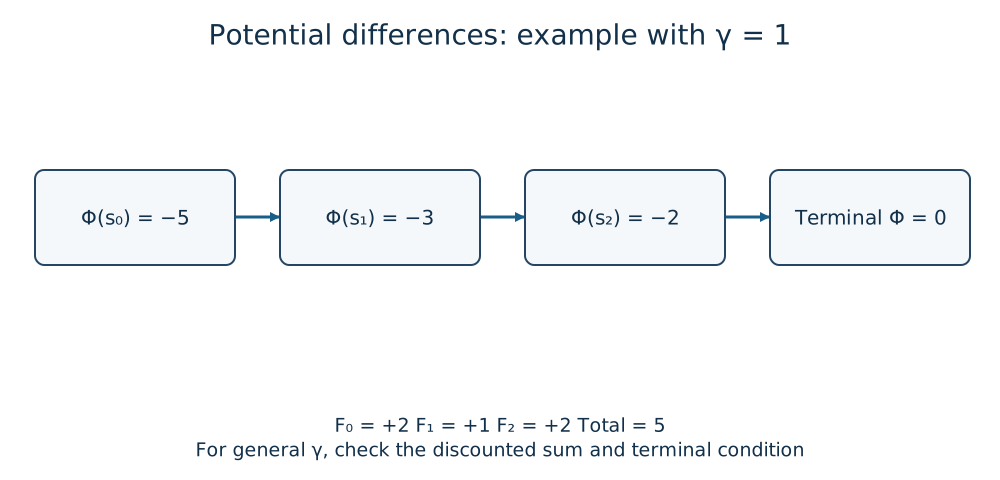 Reinforcement Learning Primer
September 4, 2026
Reward Design Primer — Why "What to Maximize" Is the Hardest Part of RL
In reinforcement learning implementations, reward-function design more often determines the outcome than the algorithm does. This article organizes sparse vs. dense reward, the policy invariance of potential-based reward shaping, real cases of reward hacking, inverse reinforcement learning, and constrained RL.
Fundamentals · 8 min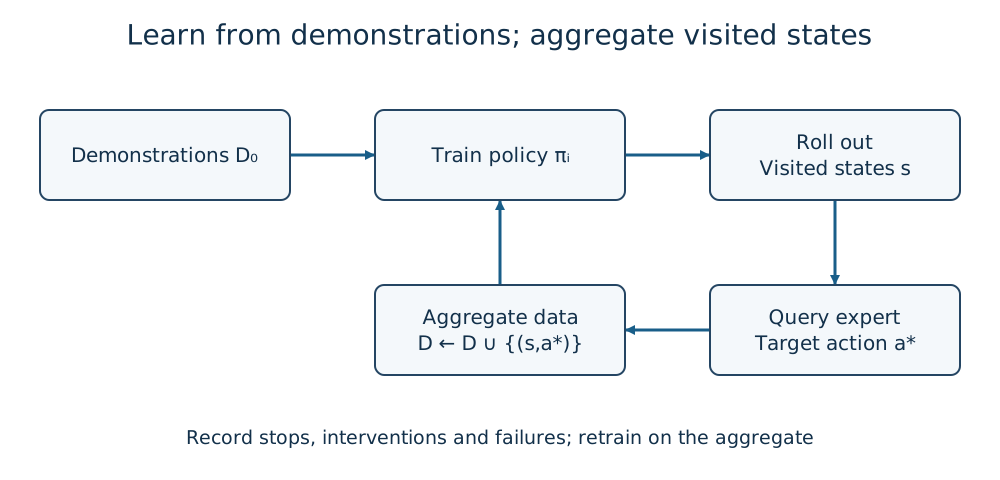 Reinforcement Learning Primer
September 3, 2026
Reinforcement Learning Primer: Imitation Learning and Inverse Reinforcement Learning
Behavior Cloning, DAgger, and inverse reinforcement learning use demonstrations when rewards are hard to write. This primer covers covariate shift, reward inference, VLA connections, evaluation, safety, and data provenance.
Fundamentals · 5 min Reinforcement Learning Primer September 3, 2026Reinforcement Learning Basics — MDPs, Bellman Equations, and Exploration for Robots
Reinforcement learning is a closed loop in which an agent chooses actions from observations and maximizes delayed rewards. This primer explains MDPs, value functions, policies, Bellman equations, exploration versus exploitation, reward design, and the path from simulation to a real robot.
Fundamentals · 6 min Reinforcement Learning Primer September 3, 2026Model-Based Reinforcement Learning and Sim-to-Real
World models, prediction error, MPC, domain randomization, system identification, and safety monitoring for real machines.
Fundamentals · 4 min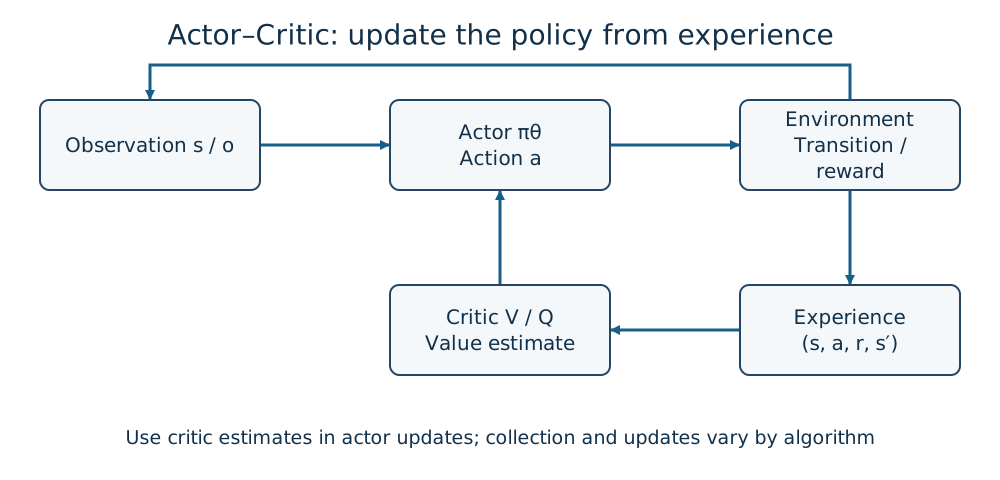 Reinforcement Learning Primer
September 3, 2026
Policy Gradients, PPO, and SAC — Stable Continuous Control for Robots
Policy gradients update a policy directly so that steering, thrust, and joint torque can remain continuous. This article connects Actor-Critic, PPO, and SAC, then covers clipping, entropy regularization, evaluation, and the safety boundary for Sim-to-Real transfer.
Fundamentals · 5 min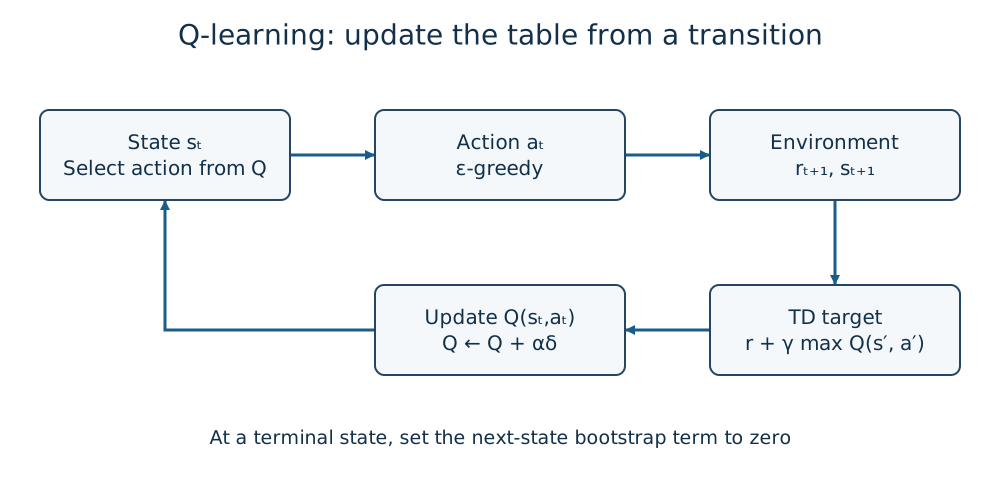 Reinforcement Learning Primer
September 3, 2026
Q-Learning and DQN — From a Q-Table to Deep Reinforcement Learning
Q-learning updates action values with the Bellman optimality target. This primer follows the path from a tabular Q-table to a Deep Q-Network, explaining experience replay, target networks, overestimation, and safe placement in a robot stack.
Fundamentals · 5 min